Architecture Overview
Introduction
Section titled “Introduction”Viglet Turing is an open-source enterprise search platform that combines semantic navigation, generative AI, tool calling, and AI Agents. It allows organizations to index content from multiple sources, apply Retrieval-Augmented Generation (RAG) over that content, and expose rich search experiences through REST and GraphQL APIs.
Content ingestion is handled by Viglet Dumont, a separate project that runs connectors independently and delivers indexed documents to Turing via an asynchronous message queue.
This document describes the system’s components, internal modules, and the two core data flows: indexing and search.
High-Level Component Diagram
Section titled “High-Level Component Diagram”
The architecture is organized into four layers: Clients & External Services at the top, an API gateway in the middle, Core Modules for business logic, and Backends & Storage at the bottom. Each layer is detailed below.
Clients & External Services
Section titled “Clients & External Services”%%{init: {'theme': 'base', 'themeVariables': {'fontSize': '13px', 'primaryColor': '#fff', 'primaryBorderColor': '#c0c0c0', 'lineColor': '#888', 'textColor': '#333'}}}%%graph LR subgraph Clients [" 💻 Clients "] CL1["🌐 JS SDK"] CL2["☕ Java SDK"] CL3["📱 Custom Apps"] end
subgraph External [" 🔌 External Services "] CON["📡 Dumont\nWebCrawler · DB · FS\nAEM · WordPress"] KC["🔑 Keycloak\nOAuth2 / OIDC"] LLM["🧠 LLM Providers\nClaude · OpenAI\nAzure · Gemini · Ollama"] end
classDef blue fill:#dbeafe,stroke:#4A90D9,stroke-width:2px,color:#1a1a1a classDef amber fill:#fef3c7,stroke:#E8A838,stroke-width:2px,color:#1a1a1a
class CL1,CL2,CL3 blue class CON,KC,LLM amber
style Clients fill:#4A90D920,stroke:#4A90D9,stroke-width:2px,color:#1a1a1a,font-weight:700 style External fill:#E8A83820,stroke:#E8A838,stroke-width:2px,color:#1a1a1a,font-weight:700| Component | Description |
|---|---|
| JS SDK / Java SDK | Typed clients for search and indexing: available on npm and Maven Central |
| Dumont | Separate application that runs connectors and sends documents to Turing via REST API |
| Keycloak | Optional OAuth2 / OIDC provider for production SSO |
| LLM Providers | Six supported vendors: Anthropic Claude, OpenAI, Azure OpenAI, Google Gemini, Gemini (OpenAI-compatible), Ollama |
API Layer
Section titled “API Layer”%%{init: {'theme': 'base', 'themeVariables': {'fontSize': '13px', 'primaryColor': '#fff', 'primaryBorderColor': '#c0c0c0', 'lineColor': '#888', 'textColor': '#333'}}}%%graph LR subgraph API [" 🌐 API Layer "] REST["📡 REST API\nSearch · Indexing · GenAI Chat\nToken Usage · Admin"] GQL["📊 GraphQL API\nSearch queries"] ADMIN["🛠️ Admin Console\nReact + TypeScript + shadcn/ui\nSN Config · Assets · Chat"] end
classDef blue fill:#dbeafe,stroke:#4A90D9,stroke-width:2px,color:#1a1a1a
class REST,GQL,ADMIN blue
style API fill:#4A90D920,stroke:#4A90D9,stroke-width:2px,color:#1a1a1a,font-weight:700| Component | Package | Description |
|---|---|---|
| REST API | api |
Controllers for search, indexing, GenAI chat, agents, token usage, and administration |
| GraphQL API | api |
Search query resolvers as an alternative to REST |
| Admin Console | turing-react |
SN Site configuration, Assets file manager (MinIO), Chat interface, Token Usage dashboard |
| Security | spring/security |
Session-based auth (console) + API Key header (REST) + optional Keycloak OAuth2/OIDC |
Core Modules
Section titled “Core Modules”%%{init: {'theme': 'base', 'themeVariables': {'fontSize': '13px', 'primaryColor': '#fff', 'primaryBorderColor': '#c0c0c0', 'lineColor': '#888', 'textColor': '#333'}}}%%graph TB subgraph Core [" ⚙️ Core Modules "] SN["🔍 Semantic Navigation\nQuery processing · Facets\nSpotlights · Targeting Rules\nAutocomplete · Highlighting"] GENAI["🤖 GenAI / RAG Engine\nTool Calling (27 tools)\nAI Agents · MCP Servers\nEmbedding pipeline"] IDX["📥 Indexing Pipeline\nArtemis queue consumer\nMerge Providers\nField mapping · Spotlights"] SE["🔧 Search Engine Plugins\nSolr (recommended)\nElasticsearch · Lucene"] end
SN --> SE GENAI -.-> SN IDX -.-> SE
classDef purple fill:#ede9fe,stroke:#9B6EC5,stroke-width:2px,color:#1a1a1a classDef green fill:#dcfce7,stroke:#50B86C,stroke-width:2px,color:#1a1a1a
class SN,GENAI,IDX purple class SE green
style Core fill:#9B6EC520,stroke:#9B6EC5,stroke-width:2px,color:#1a1a1a,font-weight:700| Module | Package | Responsibility |
|---|---|---|
| Semantic Navigation | sn |
Core search orchestration: query processing, facets, spotlights, targeting rules, autocomplete |
| Search Engine Plugins | se / plugins/se |
Abstraction layer over Solr (recommended), Elasticsearch, and Lucene |
| GenAI / RAG | genai |
RAG over SN content and MinIO assets; LLM context building and invocation |
| Tool Calling | genai/tool |
27 native tools: SN search (15), RAG/KB (4), web crawler (2), finance (2), weather (1), image search (1), datetime (1), code interpreter (1); plus MCP servers |
| LLM Providers | genai/provider/llm |
Pluggable provider factory: Anthropic, OpenAI, Azure OpenAI, Gemini, Gemini-OpenAI, Ollama |
| AI Agents | agent |
Composition of LLM Instance + Tools + MCP Servers into deployable assistants |
| Indexing Pipeline | indexer |
Receives documents via Artemis, applies Merge Providers, writes to Solr and embedding stores |
| Message Queue | artemis |
Apache Artemis: async communication between Dumont and the indexing pipeline |
| OCR | ocr |
Text extraction from PDFs, Word documents, and images via Apache Tika |
| Persistence | persistence |
JPA entities, repositories, DTOs, and MapStruct mappers for all domain objects |
Backends & Storage
Section titled “Backends & Storage”%%{init: {'theme': 'base', 'themeVariables': {'fontSize': '13px', 'primaryColor': '#fff', 'primaryBorderColor': '#c0c0c0', 'lineColor': '#888', 'textColor': '#333'}}}%%graph LR subgraph Storage [" 💾 Backends & Storage "] SOLR["🔎 Apache Solr\n+ Zookeeper\nPrimary search index"] EMB["🧬 Embedding Stores\nChromaDB · PgVector\nMilvus"] DB["🗄️ Database\nMariaDB / MySQL\nPostgreSQL · H2 (dev)"] MINIO["📦 MinIO\nAsset / file storage"] MONGO["📋 MongoDB\nApplication logs\n(optional)"] end
classDef green fill:#dcfce7,stroke:#50B86C,stroke-width:2px,color:#1a1a1a
class SOLR,EMB,DB,MINIO,MONGO green
style Storage fill:#50B86C20,stroke:#50B86C,stroke-width:2px,color:#1a1a1a,font-weight:700| Backend | Purpose | Notes |
|---|---|---|
| Apache Solr | Primary search index | SolrCloud mode with Zookeeper in production |
| Embedding Stores | Vector storage for RAG | One active per deployment: details |
| Database | Configuration, metadata, spotlights | H2 for dev; MariaDB/MySQL for production |
| MinIO | Asset/file object storage | Managed via admin console Assets file manager |
| MongoDB | Application log persistence | Optional: custom Logback appender, browsable in admin console |
| MongoDB / Redis (Chat Analytics) | Chat session metadata + AI enrichment | Optional, engine-agnostic via turing.logging.engine; powers Chat Analytics |
Observability Layer
Section titled “Observability Layer”Independent of all the above, an optional observability layer instruments every LLM call, search, snapshot lookup, and chat-analytics enrichment cycle. Spring Boot Actuator exposes /actuator/prometheus; Prometheus scrapes it; Grafana renders four pre-built dashboards (search health, search insights, search-term detail, chat insights).
%%{init: {'theme': 'base', 'themeVariables': {'fontSize': '13px', 'primaryColor': '#fff', 'primaryBorderColor': '#c0c0c0', 'lineColor': '#888', 'textColor': '#333'}}}%%graph LR    subgraph Obs [" 📊 Observability "]        ACT["📡 Spring Actuator\n/actuator/prometheus"]        PROM["📊 Prometheus\nScrape interval 5s"]        GRAF["📈 Grafana\n4 pre-built dashboards"]    end
    ACT --> PROM --> GRAF
    classDef orange fill:#fed7aa,stroke:#EA580C,stroke-width:2px,color:#1a1a1a    class ACT,PROM,GRAF orange
style Obs fill:#EA580C20,stroke:#EA580C,stroke-width:2px,color:#1a1a1a,font-weight:700| Component | Role | Notes |
|---|---|---|
| Actuator | Metrics endpoint | Built into Spring Boot; no extra dependency |
| Micrometer + Observation API | Metric/trace emission | Stable metric names defined in TurMeterNames; same observation produces both timer + span (OTel bridge) |
| Prometheus | Time-series scrape & store | containers/prometheus/prometheus.yml is the local-dev config |
| Grafana | Dashboards over metrics + Chat Analytics | Provisioning under containers/grafana/ |
The Chat Analytics dashboard reads from Turing’s REST API (engine-agnostic JSON over HTTP) via the Infinity datasource: independent of Prometheus. See Observability for full coverage.
Indexing Flow
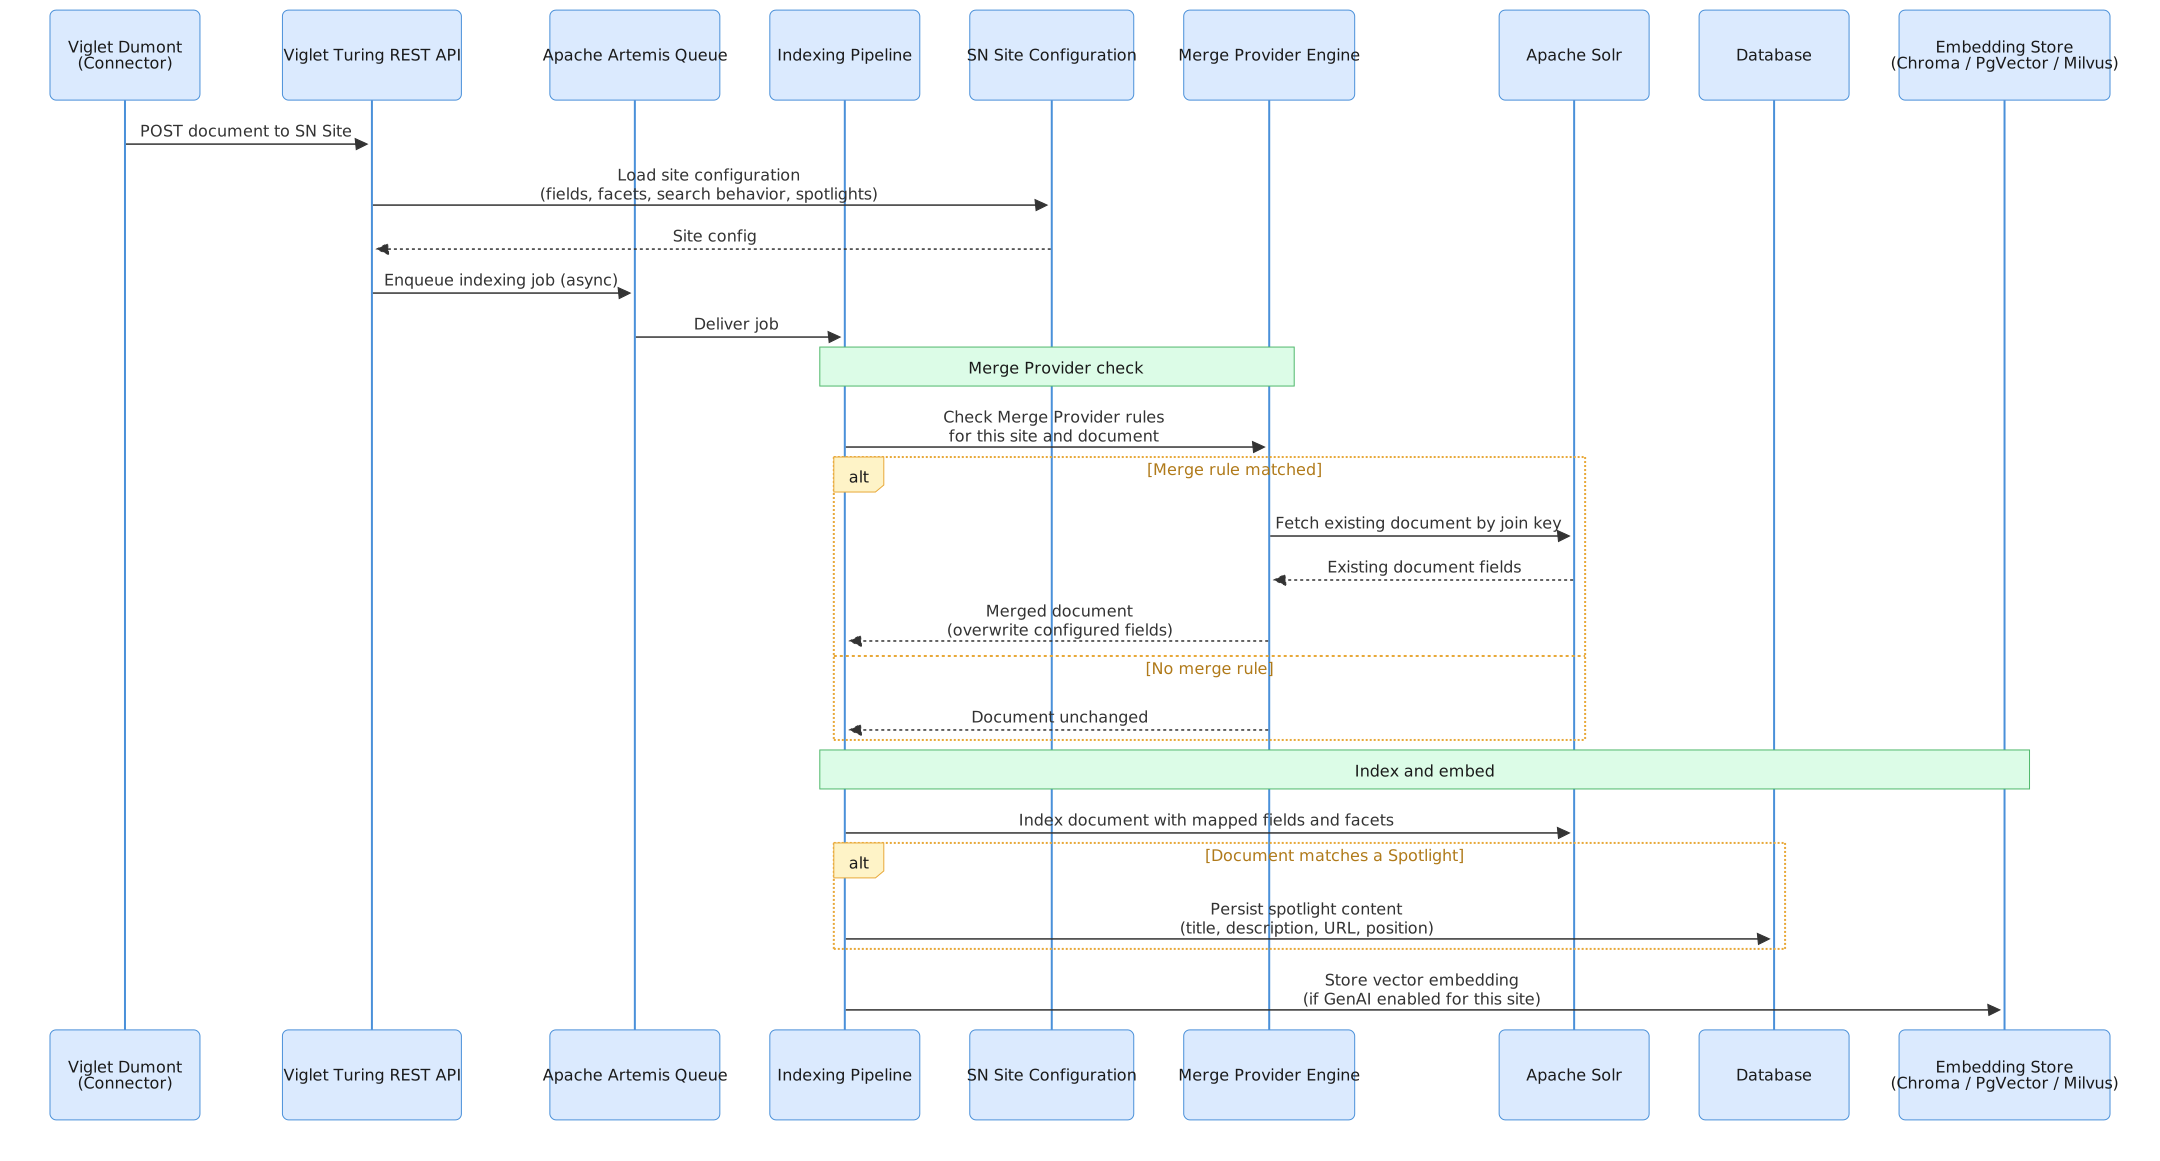
Section titled “Indexing Flow”Content ingestion is handled externally by Viglet Dumont. Each connector runs as an independent process and sends documents to Turing via its REST API. The API receives the request, validates it against the target Semantic Navigation Site configuration, and creates an indexing job that is queued internally via Apache Artemis for asynchronous processing.
The Semantic Navigation Site is the central configuration artifact that drives the entire indexing behavior: it defines which Solr instance to use, which fields the documents carry, how those fields are mapped and used (title, text, URL, date, image, facets, etc.), how search will behave, and which spotlights are configured. The indexing pipeline reads this configuration to know exactly what to do with each incoming document.
Key indexing concepts
Section titled “Key indexing concepts”REST API as entry point: Dumont connectors send documents to Turing via REST API, not by writing directly to Solr or the queue. The API is the single integration point: it validates the request, loads the target SN Site configuration, and enqueues an indexing job via Apache Artemis for asynchronous processing.
SN Site as the indexing blueprint: Every indexing job is bound to a Semantic Navigation Site. The site configuration defines the complete indexing contract: which Solr collection to write to, which document fields exist and how they are typed, which fields become facets, how highlighting and autocomplete will work, and which spotlights are active. The pipeline reads this configuration at job execution time to determine field mappings, facet assignments, and spotlight handling.
Spotlight persistence: When an incoming document matches a configured Spotlight (for example, its URL or ID matches a spotlight term) the pipeline indexes the document in Solr normally and also persists the spotlight content (title, description, URL, position) in the relational database. This ensures the spotlight data remains available for injection even if the document is later removed from the Solr index.
Viglet Dumont: The connector system that feeds Turing. It runs as a separate application and manages its own connector lifecycle (schedules, credentials, field mappings). Connectors currently available in Dumont include WebCrawler (Nutch-based), Database, FileSystem, AEM, and WordPress. Refer to the Dumont documentation for connector configuration.
Merge Providers: When two Dumont connectors independently index different representations of the same real-world document (for example, AEM indexing structured metadata from model.json and WebCrawler indexing the rendered HTML of the same page) the Merge Provider identifies them as the same document using a configured join key and merges their fields before writing to Solr. See Semantic Navigation for a detailed explanation.
Embedding stores: If Generative AI is enabled for an SN Site, a vector embedding is generated for each indexed document and written to the configured embedding store. Turing supports three embedding backends via Spring AI: ChromaDB, PgVector (PostgreSQL extension), and Milvus. Only one is active per deployment. The default embedding store and embedding model are defined globally in Administration → Settings.
MinIO asset indexing: Turing includes an Assets file manager in the admin console, backed by MinIO as the object storage layer. Files are uploaded via drag-and-drop, organized into folders, and automatically indexed as vector embeddings on upload (and unindexed on deletion). A batch “Train AI with Assets” operation processes all files using Apache Tika for text extraction, chunking at 1,024 characters, and storing embeddings in the active vector store.
Application logs in MongoDB: When MongoDB is configured, Turing ships with a custom Logback appender that extends ch.qos.logback. Every log entry generated by the application (including indexing events, search requests, errors, and system events) is persisted to MongoDB in addition to standard output. These logs are exposed in the admin console, giving administrators full visibility into application behavior without requiring access to the server file system or a separate log management tool.
Search Flow
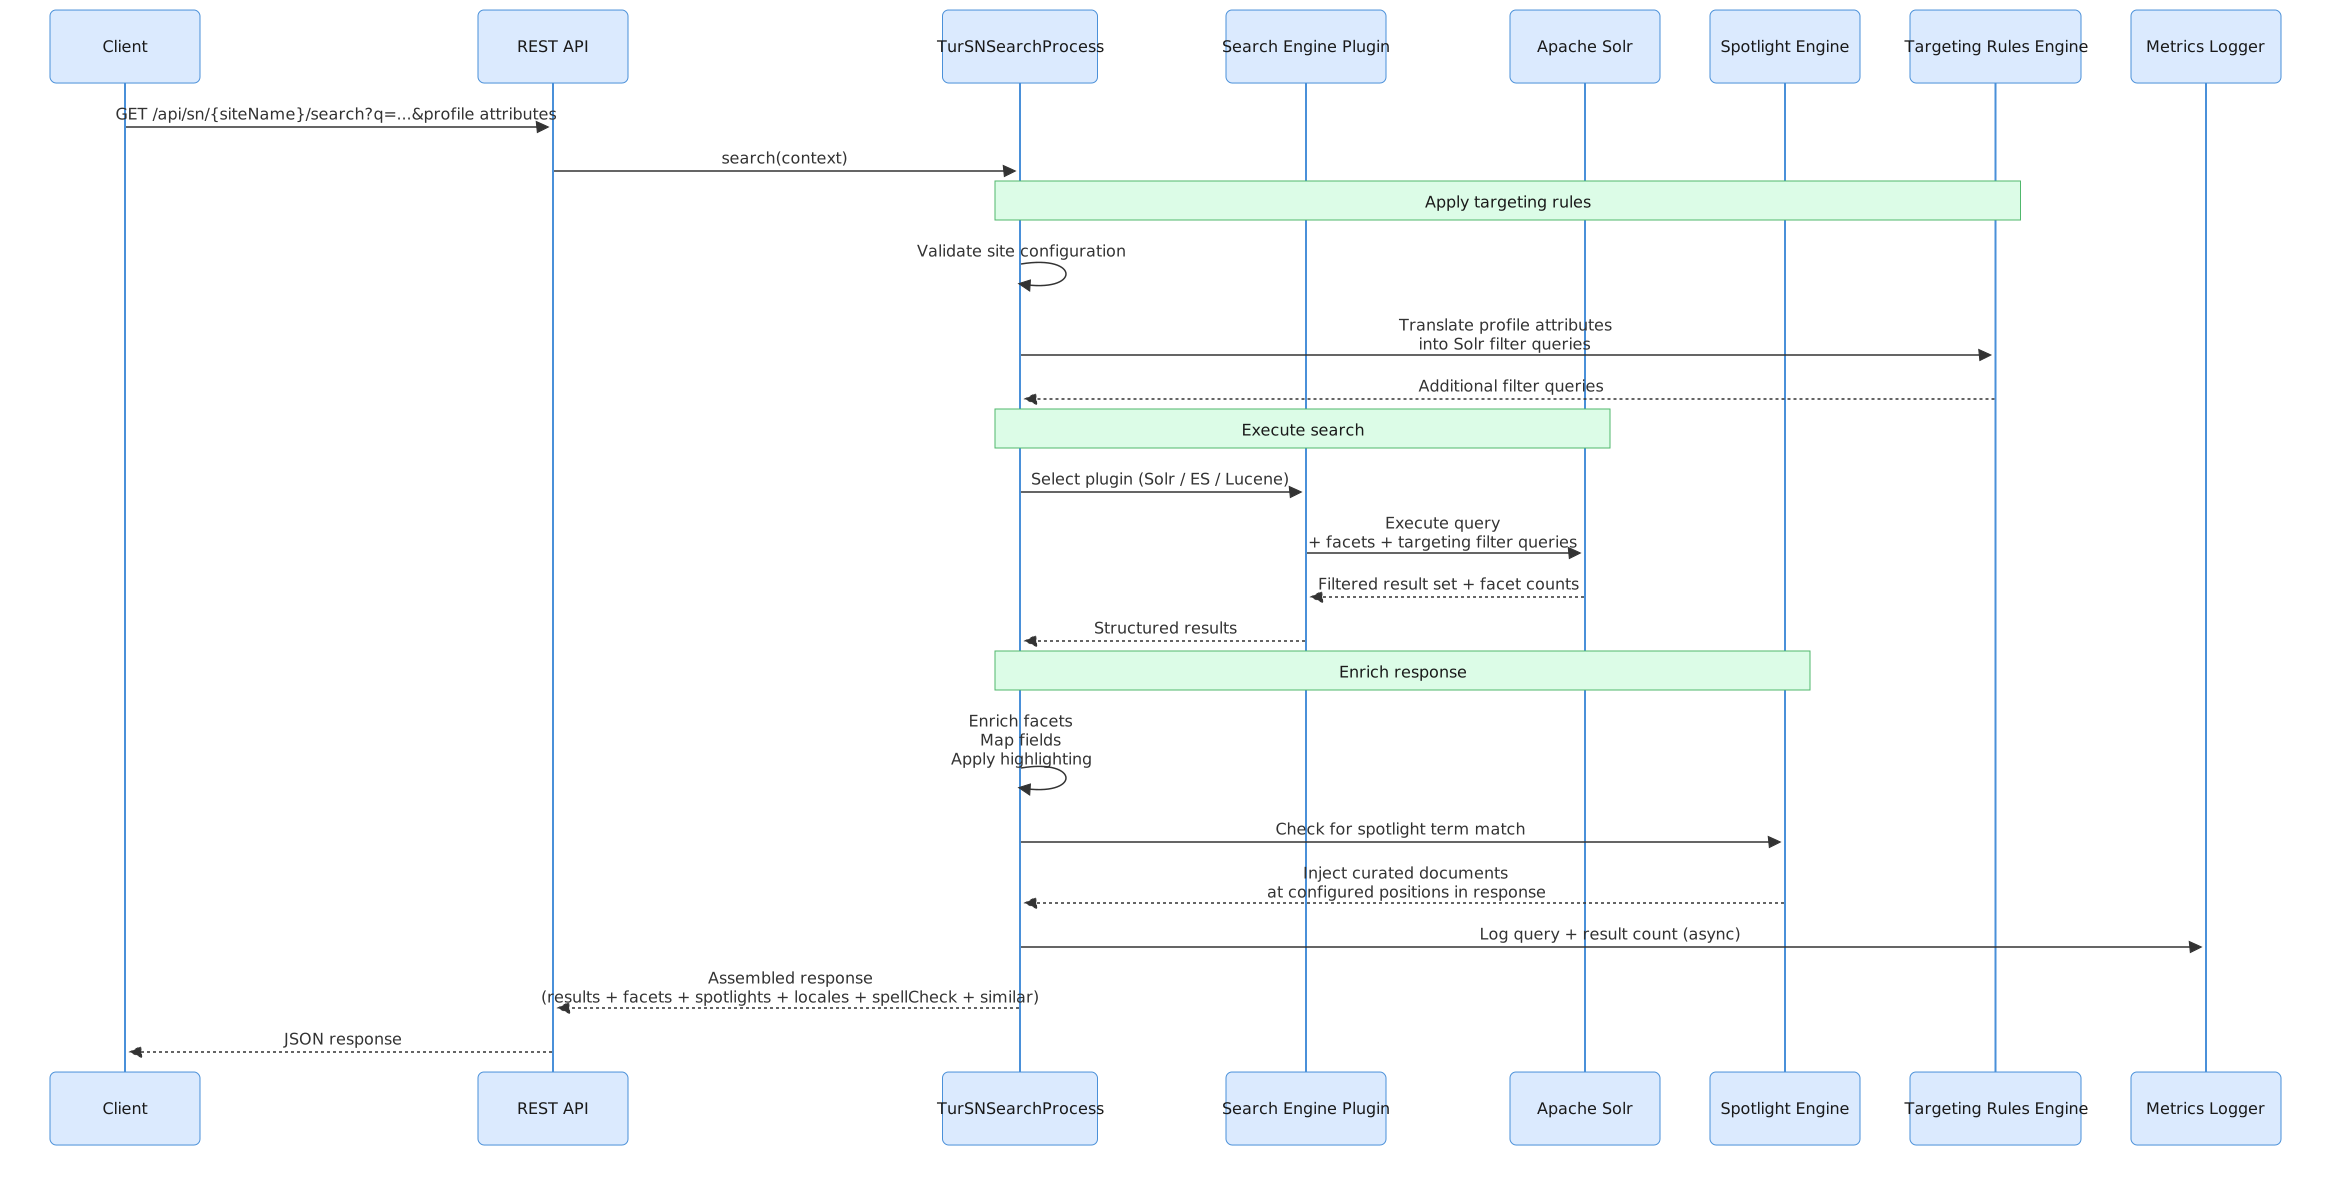
Section titled “Search Flow”The search flow is synchronous and request-driven. Every request goes through a structured pipeline before a response is returned to the client.
Key search concepts
Section titled “Key search concepts”Site-scoped execution: Every search request is scoped to a named Semantic Navigation Site. The site configuration defines which search engine backend to use, how many results per page, facet definitions, field mappings, whether Spotlights and Targeting Rules are active, and whether GenAI is enabled.
Plugin abstraction: The orchestrator does not query the search backend directly. An intermediate plugin layer translates the abstract search context into backend-specific queries, supporting Apache Solr, Elasticsearch, and Lucene as backends. Solr is the recommended production backend as it provides the most complete feature set, including full support for facets, spotlights, targeting rules, highlighting, and autocomplete. Elasticsearch and Lucene are available as alternatives with a reduced feature set.
Spotlight injection: After retrieving organic results, the system checks whether any configured Spotlights match the current query. Matching Spotlights insert curated documents at specific positions in the result list. See Semantic Navigation for details.
Targeting Rules: Results are filtered based on the requesting user’s profile attributes, passed in the request context. Targeting Rules translate those attributes into additional Solr filter queries. See Semantic Navigation for details.
Field mapping and highlighting: Before returning results, each document’s fields are remapped to a canonical set of display fields configured per site (title, description, text, date, image, URL). Highlighting wraps matched terms with configurable HTML tags (default: <mark>).
Metrics: After assembling the response, query metrics (search term, result count, site, timestamp) are logged asynchronously to avoid adding latency to the response.
Technology Stack
Section titled “Technology Stack”| Layer | Technology | Notes |
|---|---|---|
| Runtime | Java 21 | Minimum supported version |
| Framework | Spring Boot + Spring AI | Application container; Spring AI powers LLM and embedding integrations |
| Search Engine | Apache Solr (recommended), Elasticsearch, Lucene | Solr is the primary production backend with the most complete feature set; Elasticsearch and Lucene are supported as alternatives |
| Solr Coordination | Apache Zookeeper | Required for Solr in production (SolrCloud mode) |
| Message Broker | Apache Artemis | Asynchronous indexing queue (embedded in Turing) |
| Database | H2 / MariaDB / MySQL / PostgreSQL | H2 for development; MariaDB or MySQL recommended for production |
| Embedding Stores | ChromaDB / PgVector / Milvus | Via Spring AI; one backend active per deployment |
| Asset Store | MinIO | External service; configured in application.yaml (host, user, password); object storage for files managed via the admin console folder UI |
| Log Store | MongoDB | Optional; custom Logback appender (ch.qos.logback) persists all application logs to MongoDB, accessible via the admin console |
| LLM Providers | Anthropic Claude, OpenAI, Azure OpenAI, Google Gemini, Gemini (OpenAI-compatible), Ollama | Configured per site or globally; one active at a time |
| Tool Calling | 27 native tools across 7 categories + MCP (external servers) | Semantic Nav (15), RAG/KB (4), Web Crawler (2), Finance (2), Weather (1), Image Search (1), DateTime (1), Code Interpreter (1); MCP via HTTP or stdio |
| Identity Management | Keycloak | OAuth2 / OpenID Connect; optional for deployments without SSO |
| Load Balancer | Apache HTTP Server | Optional; required for high-availability cluster deployments |
| Connector System | Viglet Dumont | Separate application; sends documents to Turing via REST API, which queues them internally to Artemis |
| Build System | Apache Maven | Multi-module project |
| Frontend | React + TypeScript + shadcn/ui + Vite | Admin console (turing-react): includes SN configuration, Assets manager, Chat interface, Token Usage dashboard |
| Containerization | Docker / Docker Compose | Available in containers/ directory |
| Orchestration | Kubernetes | Manifests available in k8s/ directory |
| API Protocols | REST + GraphQL | Swagger UI available in development mode |
| Java SDK | turing-java-sdk |
Available on Maven Central; typed client for search and indexing |
| JavaScript SDK | @viglet/turing-sdk |
Available on npm; TypeScript-ready client for web and Node.js |
Deployment Topologies
Section titled “Deployment Topologies”Turing supports several deployment configurations. Each builds on the previous one: start with what you need and add components as requirements grow.
Development
Section titled “Development”Minimal setup for local development and evaluation.
Turing (H2 embedded) + Apache SolrTuring starts with an embedded H2 database. No external database is needed. Not suitable for production.
Simple Production
Section titled “Simple Production”Recommended baseline for production environments.
Turing + Apache Solr + Zookeeper + MariaDB / MySQLSolr runs in SolrCloud mode coordinated by Zookeeper, enabling index replication and fault tolerance at the Solr layer. MariaDB or MySQL provides durable persistence for Turing configuration and metadata.
Production with Security (SSO)
Section titled “Production with Security (SSO)”For environments that require integration with an identity provider or corporate SSO.
Turing + Apache Solr + Zookeeper + MariaDB / MySQL + KeycloakKeycloak handles authentication via OAuth2 / OpenID Connect. Users log in through Keycloak and receive tokens that are validated by Turing. See Security & Keycloak for configuration details.
Production with Log UI
Section titled “Production with Log UI”For environments where administrators need visibility into application behavior directly from the Turing admin console, without access to server logs or external log tools.
Turing + Apache Solr + Zookeeper + MariaDB / MySQL + MongoDBWhen MongoDB is configured, a custom Logback appender persists every log entry generated by the application to MongoDB. The admin console exposes these logs in a searchable interface, showing errors, warnings, indexing events, and system activity in real time.
High Availability
Section titled “High Availability”For environments requiring horizontal scaling and zero-downtime deployments.
Apache HTTP Server (load balancer) └── Turing node 1 └── Turing node 2 └── Turing node NApache Solr + Zookeeper (cluster)MariaDB / MySQL (primary + replica)Keycloak (optional)MongoDB (optional)Multiple Turing instances run behind Apache HTTP Server configured as a reverse proxy and load balancer. Solr runs as a multi-node SolrCloud cluster. The database should be configured with at least one replica for redundancy.
Related Pages
Section titled “Related Pages”| Page | Description |
|---|---|
| Installation Guide | Setup with Docker, JAR, or build from source |
| Configuration Reference | All application.yaml properties |
| Integration | Manage content connectors in the admin console |
| Dumont: Architecture | Connector-side architecture: pipeline engine, message queue, and indexing plugins |
| Dumont: Connectors | Available connectors and deployment types |